Reddit Data API: Access, Limits, Pricing and Terms
Try Gologin for free
Reddit is one of the largest collections of real conversations on the internet, so it is no surprise that marketers, researchers and developers want its data. The way Reddit allows is its Data API. This guide covers how to get access, the rate limits, what it costs and what the terms say.
Reddit takes this seriously. Since 2023 it charges for large-scale API use, and it has gone to court against companies that collected its content without permission. If you need Reddit data for a product or a research project, start with the API, not with a scraper.
What is the Reddit Data API?
The Reddit Data API is the official way for apps and scripts to read and write Reddit content: posts, comments, subreddits, votes and the actions of the account that uses the app. It is a REST API at oauth.reddit.com, and every request needs an OAuth token.
The API is free within its limits for personal projects, moderator tools and non-commercial research. Commercial use and large volumes need a separate agreement with Reddit.
How to get access
- Read the terms first. Reddit’s Developer Terms and Data API Terms apply to every app, along with its Responsible Builder Policy. Reddit reviews new API access, so check the current request process in its developer documentation before you build.
- Register your app. While logged in to Reddit, open the app preferences page (
reddit.com/prefs/apps) and create an app. Choose the type: script for a personal script, web app for a server app, or installed app for a mobile or desktop app. - Get your credentials. Reddit gives you a client ID and, for script and web apps, a client secret. Keep them private.
- Authenticate with OAuth2. Exchange your credentials for an access token and send it with every request.
- Set a clear User-Agent. Reddit asks for a unique, descriptive User-Agent with your app name, version and Reddit username, for example
platform:myapp:v1.0 (by /u/yourname). Generic or fake User-Agents get throttled or blocked.
Rate limits
Reddit’s published limits for the free tier are:
- 100 queries per minute per OAuth client ID, averaged over a 10-minute window;
- requests without OAuth are heavily limited and may be blocked.
Every response carries headers that tell you where you stand: X-Ratelimit-Used, X-Ratelimit-Remaining and X-Ratelimit-Reset. Read them and slow down before you hit zero. If your project needs more, ask Reddit for a higher limit or a commercial agreement. Do not register extra apps or accounts to multiply your quota: the terms do not allow it.
Pricing
Reddit does not publish a price list for commercial access. When it introduced paid access in 2023, it said large-scale users would pay about $0.24 per 1,000 API calls. Today commercial and high-volume access is agreed by contract with Reddit, and the price depends on the use case.
What stays free, within the limits above:
- personal scripts and bots on your own account;
- moderator tools and apps that help moderators;
- accessibility apps;
- non-commercial academic research, under Reddit’s research access rules.
Companies that need Reddit content at scale, for example to train AI models, sign data licensing agreements with Reddit. Brands that only want to follow conversations about themselves can also use Reddit’s own business tools, such as Reddit Pro.
What the terms say
The Developer Terms and the Data API Terms are long, but a few rules matter for almost every project:
- No commercial use without an agreement. If you make money from an app that uses Reddit data, you need Reddit’s approval.
- No model training without permission. You may not use Reddit content to train machine learning or AI models unless Reddit agrees to it in writing.
- Respect deletions. When users delete their posts or accounts, your copy should go too.
- Respect user privacy. Do not try to identify users, combine their data with other sources to build profiles, or sell user data.
- Do not get around limits. No extra apps or accounts to raise your quota, and no scraping of reddit.com pages to avoid the API.
A simple example with PRAW
PRAW, the Python Reddit API Wrapper, is the most popular client for the Reddit API. It handles OAuth and waits automatically when you get close to the rate limit.
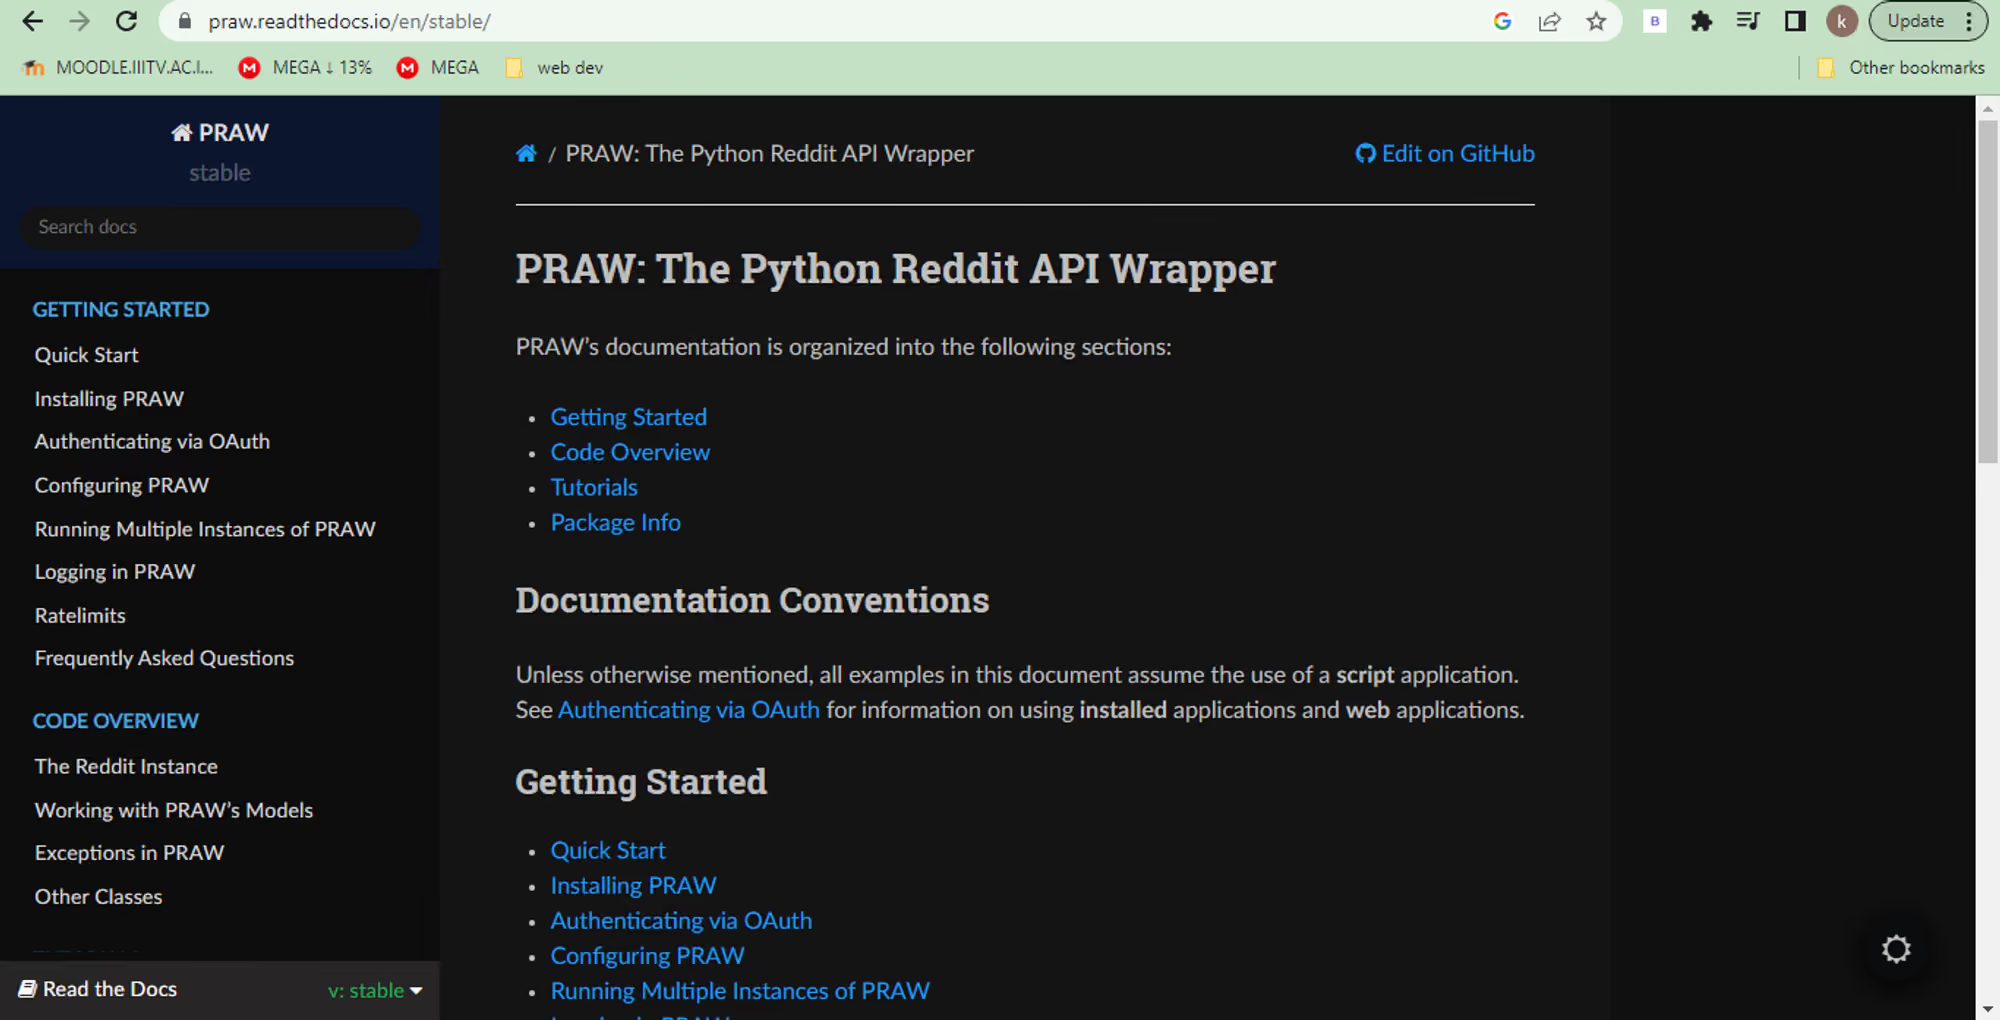
Install it with pip install praw and read the newest posts of a subreddit like this:
import praw

reddit = praw.Reddit(
    client_id="YOUR_CLIENT_ID",
    client_secret="YOUR_CLIENT_SECRET",
    user_agent="script:subreddit-reader:v1.0 (by /u/yourname)",
)

for post in reddit.subreddit("learnpython").new(limit=10):
    print(post.title, post.score, post.num_comments)
Store the client ID and secret in environment variables, not in your code, and cache results so you do not ask the API for the same data twice.
What not to do
- Scraping reddit.com or old.reddit.com pages instead of using the API.
- Rotating IP addresses, accounts or apps to get past the rate limit.
- Selling or republishing Reddit content, or using it to train models, without an agreement.
- Collecting data about individual users to build profiles of them.
Reddit can revoke your API access, ban the accounts involved and take legal action.
Frequently asked questions
Is the Reddit API free?
Yes, within the rate limits, for personal, moderator, accessibility and non-commercial research use. Commercial and high-volume use needs an agreement with Reddit.
How many requests can I make to the Reddit API?
The free tier allows 100 queries per minute per OAuth client ID, averaged over 10 minutes. Check the X-Ratelimit headers in each response.
Can I use Reddit data to train an AI model?
Not without Reddit’s written permission. The Data API Terms forbid model training unless Reddit agrees to it.
Is scraping Reddit allowed?
No. Reddit’s terms do not allow automated collection outside the API, and Reddit has sued companies that scraped it. Use the Data API, or contact Reddit about a data agreement.