ScraperAPI Review 2026: 7 Benchmark Tests, Pricing and Real Costs
Try Gologin for free
Most scraping APIs look the same on a static page. The differences show up on sites behind Cloudflare or DataDome, and in what each page costs once the credit multipliers stack up. This ScraperAPI review runs ScraperAPI, a web scraping API, and Gologin on the same seven targets, with the same runs and the same success check.
ScraperAPI sells one endpoint with credit costs that change by parameter and by site. Gologin enters as a stack: Gologin Web Unlocker for page retrieval plus Gologin Cloud Browser for jobs that need a live session.
Every number below comes from a logged run, including Gologin’s losses.
ScraperAPI vs Gologin: Key Takeaways
- Retrieval success: ScraperAPI returned the full page in 38 of 45 runs across tests 1 to 5, Web Unlocker in 44 of 45. Almost all of the gap is one target, the DataDome category page.
- DataDome target: ScraperAPI got 3/10 on the Amway category page at its best setting, premium proxies plus rendering plus US geo, at 40 credits a request. Web Unlocker got 10/10 at a median of 12.86 s with the default request.
- Where ScraperAPI was faster: Indeed (8.82 s against 12.41 s) and Walmart (6.37 s against 9.02 s), both with the default request and no rendering.
- Empty pages are billed: ScraperAPI charges every HTTP 200. On Amway it charged 10 to 40 credits for 17 pages that said “A system error has occurred” and listed no products.
- Infinite scroll: ScraperAPI’s rendering instructions loaded 100 quotes in 5/5 runs at 26.08 s. Gologin Cloud Browser did it 5/5 at 14.90 s through Playwright.
- Neither is the universal winner: ScraperAPI is cheaper on static pages and won on speed on two of five targets. The Gologin stack won the DataDome page, the JavaScript page and both browser tests.
| ScraperAPI | Gologin Web Unlocker (+ Cloud Browser for #6, #7) | |
|---|---|---|
| Success, tests 1 to 5 | 38/45 | 44/45 |
| Median time, hardest target (#4 DataDome) | 43.28 s | 12.86 s |
| Cost per 1K, hardest target (entry plan) | $19.60 | $0.98 |
| JS rendering | render=true, 10 credits | included |
| Sessions and interaction | session_number (15 min), rendering instructions | Cloud Browser, hourly |
| Charged responses | every 200 and 404 | successful pages only |
| Free trial | 5,000 credits, 7 days, no card | 1,000 requests, 7 days, no card |
What Is ScraperAPI?
ScraperAPI is a web data API: you send a URL to one endpoint and get the page back as HTML, Markdown or text. Parameters switch on JavaScript rendering, residential proxies, geo-targeting and browser actions, and each one changes the credit cost of the request.
It is built for developers and data teams that want pages without running their own proxies or browsers, paying a monthly plan in API credits.
| Product | What it does | When you use it |
|---|---|---|
| Sync API | One request, one page, with all parameters | Real-time scraping |
| Async API | Jobs and batches up to 50,000 URLs, results by status URL or webhook | Large scheduled jobs |
| Structured Data Endpoints | Parsed JSON for Amazon, Google, Walmart, eBay and others | Ready fields instead of HTML |
| DataPipeline and Crawler | Scheduled jobs and site crawls from the dashboard | No-code or recurring collection |
| MCP server | ScraperAPI as a tool for AI agents | Agents and LLM pipelines |
We ran the same kind of tests in our ScrapingBee review and our Crawlbase review.
How We Tested ScraperAPI and Gologin
Tests ran on 3 November 2026 from one machine. Each tool got 5 runs per target, extended to 10 when a run failed or the slowest run took more than twice the median, at least 10 seconds apart, with a fresh cache-busting parameter (cb=timestamp) on every URL.
| # | Scenario | Target | Success marker |
|---|---|---|---|
| 1 | Static HTML | books.toscrape.com product page | h1 and .price_color |
| 2 | JavaScript-rendered | quotes.toscrape.com/js/ | at least 10 .quote elements |
| 3 | Site behind Cloudflare | indeed.com job search, New York | h1 and a job card, no challenge |
| 4 | Site running DataDome | amway.com Skin Care category | at least 10 prices, no DataDome markup |
| 5 | Marketplace product | walmart.com item 5689919121 | product title and price |
| 6 | Infinite scroll | quotes.toscrape.com/scroll | at least 50 quotes |
| 7 | Escalation | amway.com Skin Care category | at least 10 prices |
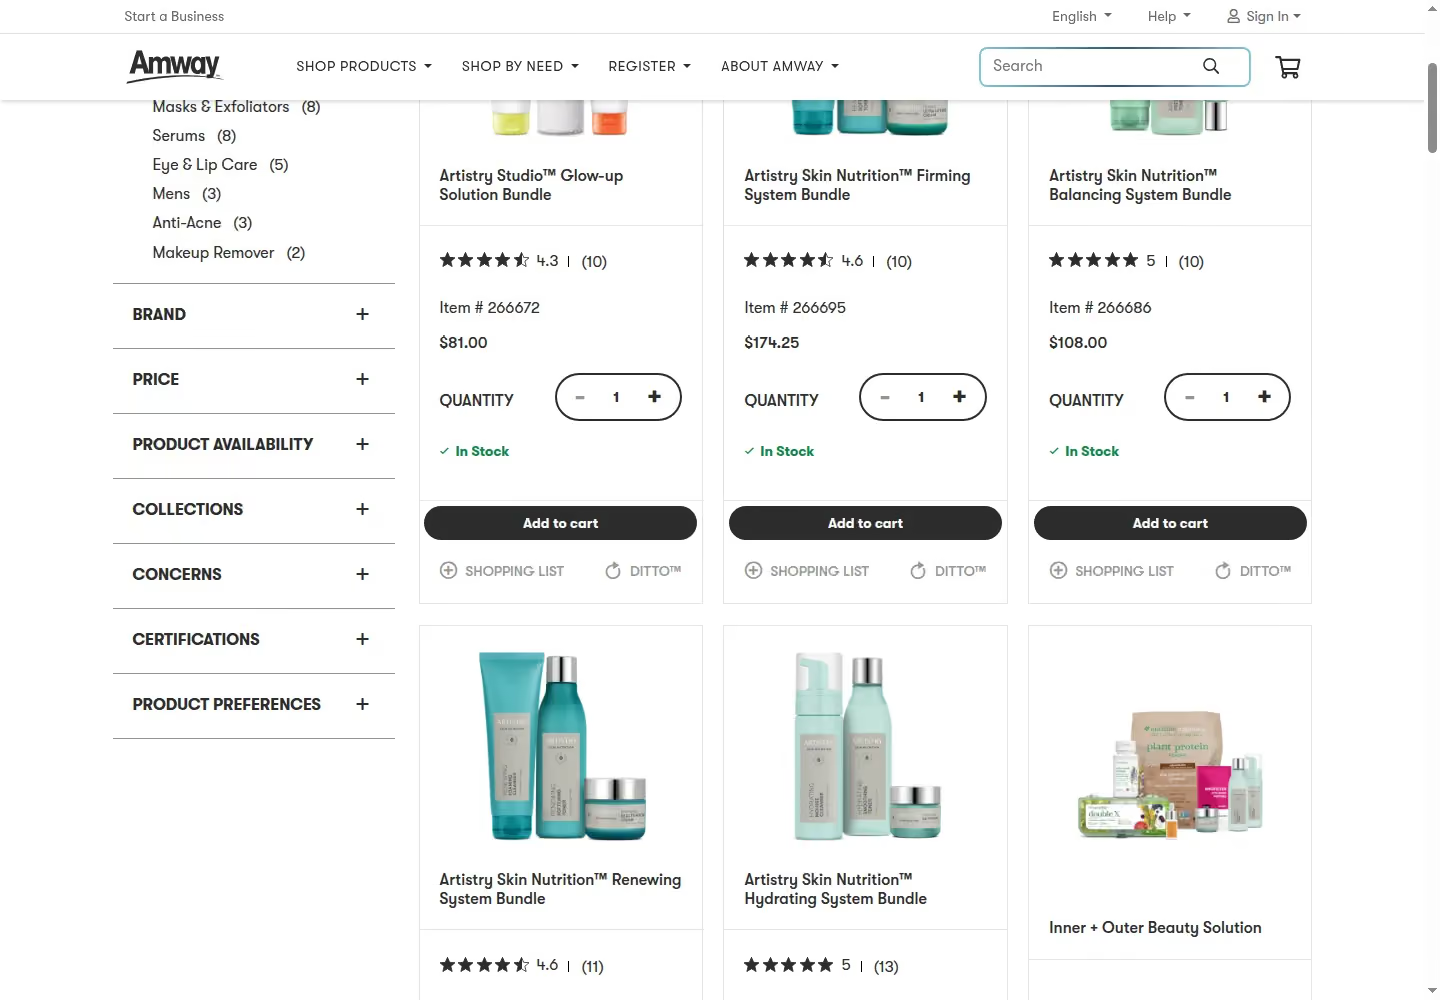
- Direct requests first: a plain request got a Cloudflare challenge from Indeed, a DataDome device check from Amway and a “Robot or human?” page from Walmart, so all three are real access tests.
- Configuration rule: ScraperAPI started on the cheapest setup and stepped up through render, premium, premium plus render and country_code=us only when the marker failed. Every step is in our log.
- Success and cost: a run counts only when one shared parser finds the marker in the body, never on HTTP 200 alone. Cost per 1,000 = price per credit x credits per request x 1,000; both vendors say failed requests are free, so there is no division by the success rate.
python -m venv .venv && source .venv/bin/activate && pip install requests beautifulsoup4 playwright python-dotenvScraperAPI ran on its free trial (5,000 credits, 7 days). The trial accepted premium=true; ultra_premium=true returned HTTP 403 with “Your current plan does not allow you to use our premium proxies”, so that tier is reported as not available on the tested plan.
ScraperAPI Features and Full API Parameters
- One endpoint, many costs: a normal request is 1 credit; render, premium and ultra_premium raise it to 10, 25, 30 or 75 (ScraperAPI docs).
- Site costs: e-commerce sites such as Walmart cost 5 credits, Google 25, LinkedIn 30, and sites behind Cloudflare, DataDome, PerimeterX or Akamai add 10.
- Cost signals: every response carries an sa-credit-cost header, and the /account/urlcost endpoint quotes a request before you send it.
- Output formats: HTML, Markdown and text for any URL, JSON or CSV through autoparse on supported sites, and screenshots.
- Geo-targeting: country_code; Hobby and Startup get only us and eu, Business and higher get the country list.
- Sticky sessions: session_number keeps one IP, sessions expire 15 minutes after last use.
- Rendering instructions: click, input, loop, scroll and wait steps sent as a header with render=true.
- Billing rule: “you are only charged for successful requests, 200 and 404 status codes.”
| Parameter | Type | Default | What it does | Cost effect |
|---|---|---|---|---|
| api_key | string | none | Account key | none |
| url | string | none | Target URL, encoded | site cost 1 to 30, +10 on sites behind Cloudflare or DataDome |
| render | boolean | false | Renders JavaScript before returning | 10 credits |
| wait_for_selector | string | none | Waits for an element, needs render | none |
| screenshot | boolean | false | PNG URL in sa-screenshot, enables render | rendering cost |
| country_code | ISO code | automatic | Routes through one country or region | none |
| premium | boolean | false | Residential and mobile IPs | 10, or 25 with render |
| ultra_premium | boolean | false | Top pool, paid plans only | 30, or 75 with render |
| session_number | integer | none | Same IP for 15 minutes, not with premium | none |
| keep_headers | boolean | false | Forwards your headers | none |
| device_type | desktop, mobile | desktop | User agent type | none |
| autoparse | boolean | false | JSON for supported sites | none |
| output_format | markdown, text, json, csv | html | Response format | none |
| follow_redirect | boolean | true | Follows redirects | none |
| max_cost | integer | none | Refuses requests above this cost | none |
| cache_control | no-cache | cache on | Skips the 10-minute ultra_premium cache | none |
| x-sapi-instruction_set | JSON header | none | Click, input, loop, scroll, wait steps | rendering cost |
- country_code=us: gave the best test #4 result, 3/10, on top of premium and render.
ScraperAPI Review: Hands-On Testing Results
Test #1: Static HTML page
We sent the books.toscrape.com product page with the default request.
from common import credits, scraperapi
from markers import static_page

TARGET = "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html"

def run(**params):
    response, elapsed = scraperapi(TARGET, **params)
    found = static_page(response.text)
    print(f"Config        : {params or 'default'}")
    print(f"HTTP status   : {response.status_code}")
    print(f"Body          : {len(response.content):,} bytes")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, found

run()
Every run returned the title and price.
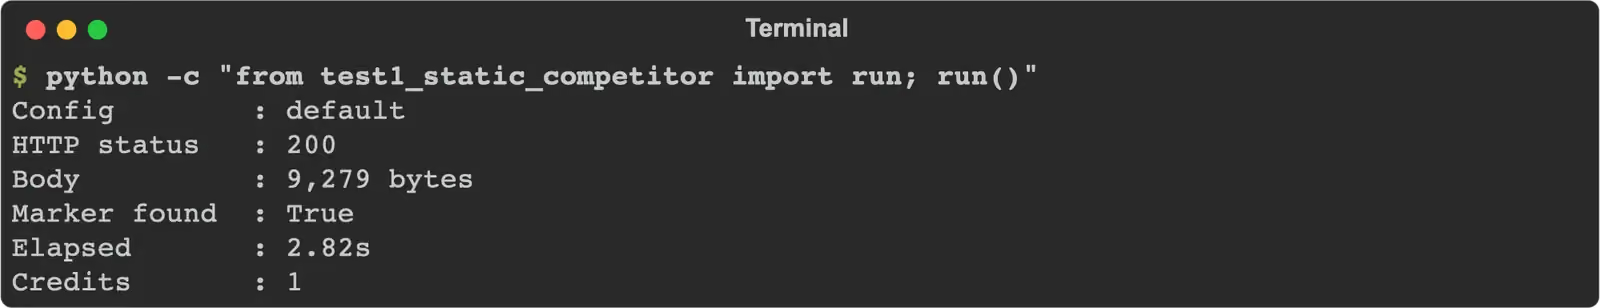
10/10 successful, median 2.69 s, 1 credit each. The slowest run took 6.40 s, more than twice the median, so the test went to 10 runs.
Test #2: JavaScript-rendered page
We sent quotes.toscrape.com/js/ with the default request, then with render=true.
from common import credits, scraperapi
from markers import js_quotes

TARGET = "https://quotes.toscrape.com/js/"

def run(**params):
    response, elapsed = scraperapi(TARGET, **params)
    found = js_quotes(response.text)
    print(f"Config        : {params or 'default'}")
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, found

run(render="true")
With rendering on, the quotes were in the body every time.
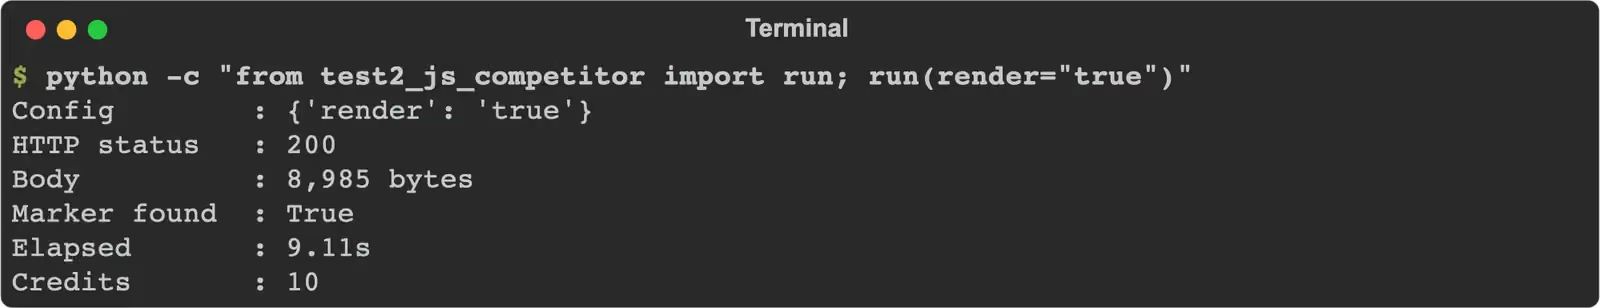
10/10 successful, median 9.84 s, 10 credits each, slowest 41.12 s. The default request got 0/5: ScraperAPI returned HTTP 200 with the unrendered page and charged 1 credit for each.
Test #3: Site behind Cloudflare
We sent an indeed.com job search, which answers a plain request with a Cloudflare challenge.
from common import credits, scraperapi
from markers import job_search

TARGET = "https://www.indeed.com/jobs?q=python+developer&l=New+York%2C+NY"

def run(**params):
    response, elapsed = scraperapi(TARGET, **params)
    found = job_search(response.text)
    print(f"Config        : {params or 'default'}")
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, found

run()
The default request returned the job list every time.
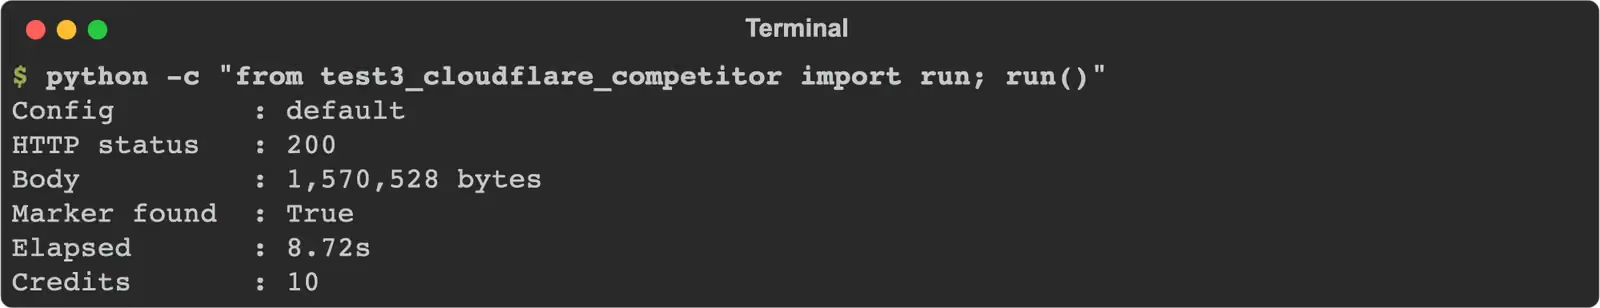
10/10 successful, median 8.82 s, 10 credits each: 1 for the request plus the 10-credit Cloudflare surcharge, as the sa-credit-cost header showed.
Test #4: Site running DataDome
We sent the Amway Skin Care category, which answers a plain request with a DataDome device check.
from common import credits, scraperapi
from markers import category_page

TARGET = "https://www.amway.com/en_US/Shop/Beauty/Skin-Care/c/105"

def run(**params):
    response, elapsed = scraperapi(TARGET, **params)
    found = category_page(response.text)
    print(f"Config        : {params or 'default'}")
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, found

run(premium="true", render="true", country_code="us")
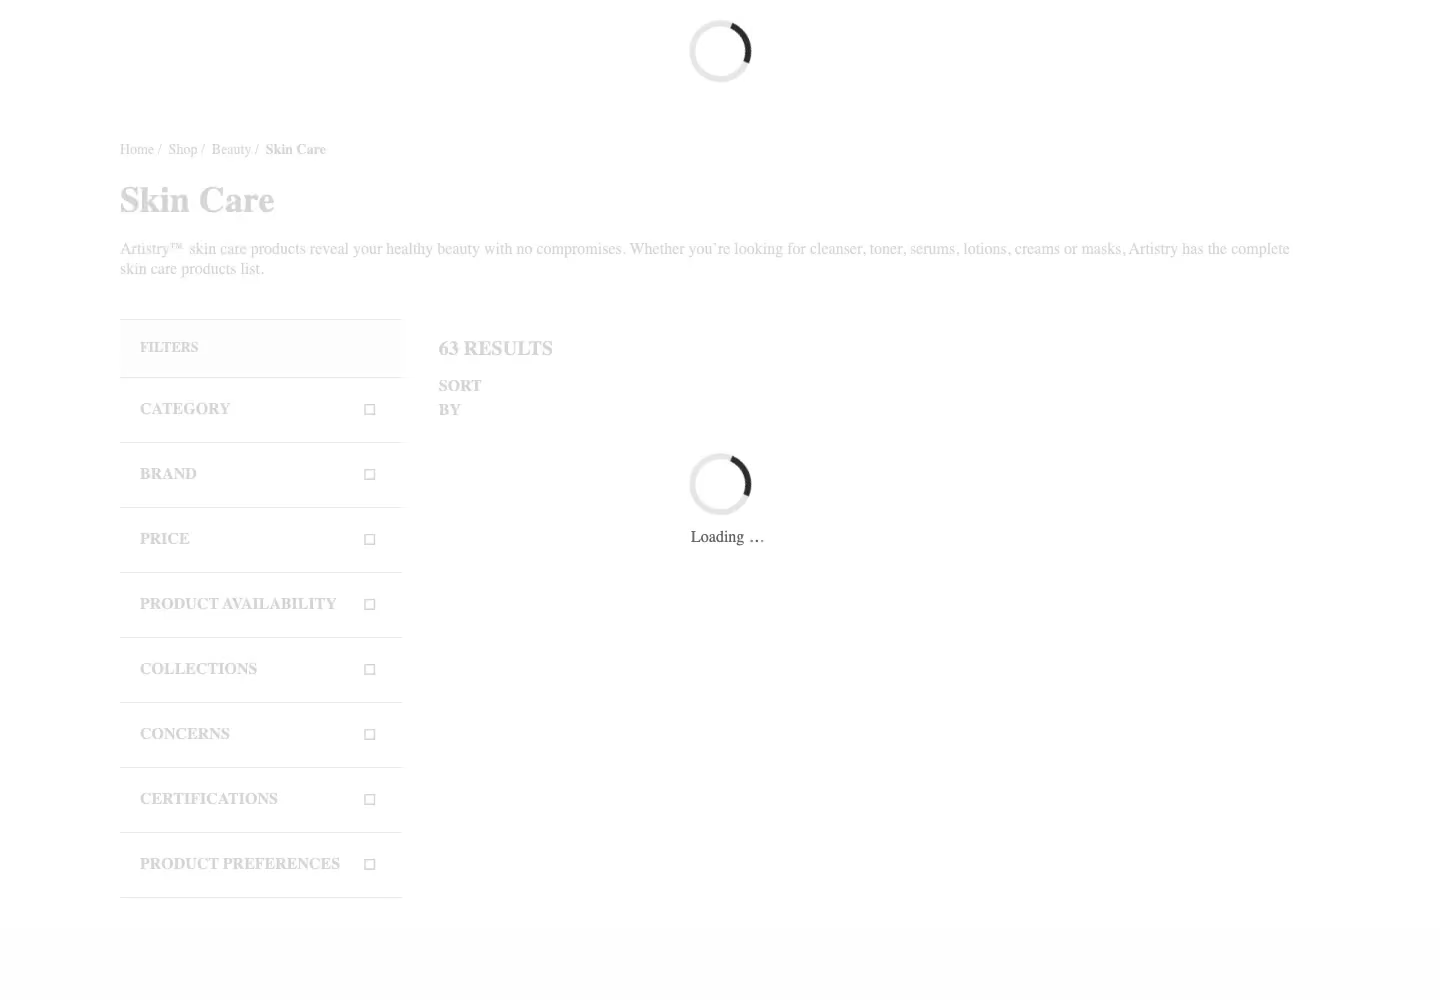
Three of ten runs returned the product grid.
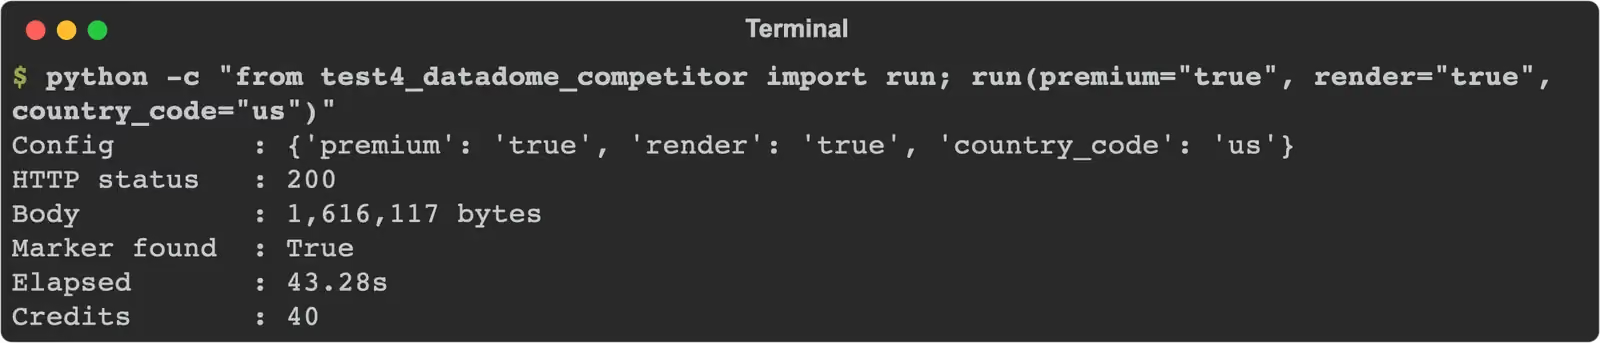
3/10 successful, median 43.28 s, 40 credits each, after the default request (0/5), render (0/5), premium (0/5) and premium plus render (1/5).
The failed runs split two ways. Some ended in HTTP 500 and were not charged. Others came back as HTTP 200 with the category frame, the text “A system error has occurred” and no products, and those were billed: 17 such pages across the steps, at 10 to 40 credits each. Test #4 used 570 credits for 4 product grids.
Test #5: Marketplace product page
We sent the Walmart product page for item 5689919121 with the default request.
from common import credits, scraperapi
from markers import product_page

TARGET = "https://www.walmart.com/ip/5689919121"

def run(**params):
    response, elapsed = scraperapi(TARGET, **params)
    found = product_page(response.text)
    print(f"Config        : {params or 'default'}")
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, found

run()
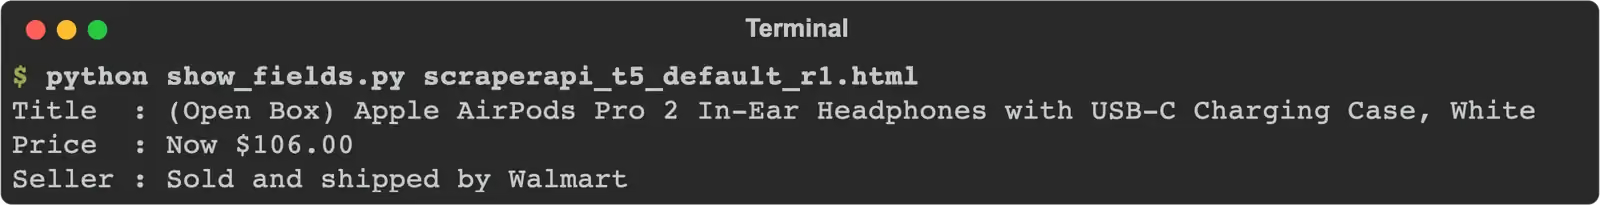
Every run returned the product title and price.
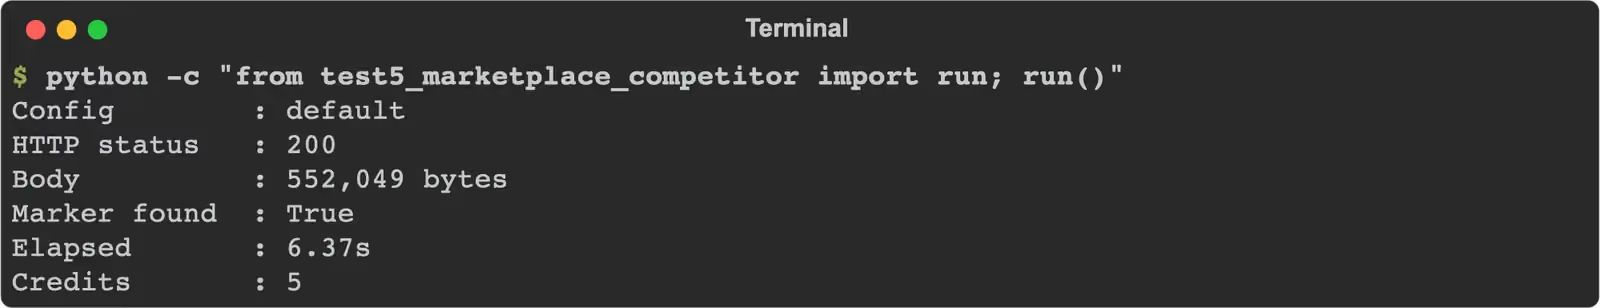
5/5 successful, median 6.37 s, 5 credits each, the documented e-commerce site cost.
Test #6: Infinite scroll
ScraperAPI has no browser product, so we used its rendering instructions: a loop of scroll and wait steps sent as a header.
from bs4 import BeautifulSoup
from common import credits, scraperapi

TARGET = "https://quotes.toscrape.com/scroll"

def scroll(times, wait):
    return [{"type": "loop", "for": times, "instructions": [
        {"type": "scroll", "direction": "y", "value": "bottom"},
        {"type": "wait", "value": wait}]}]

def run(times=6, wait=2):
    response, elapsed = scraperapi(TARGET, instructions=scroll(times, wait), render="true")
    quotes = len(BeautifulSoup(response.text, "html.parser").select("div.quote"))
    print(f"Quotes loaded : {quotes}")
    print(f"Marker found  : {quotes >= 50}")
    print(f"Elapsed       : {elapsed:.2f}s")
    print(f"Credits       : {credits(response):g}")
    return response, elapsed, quotes >= 50

run()
Six scrolls loaded all 100 quotes in every run.
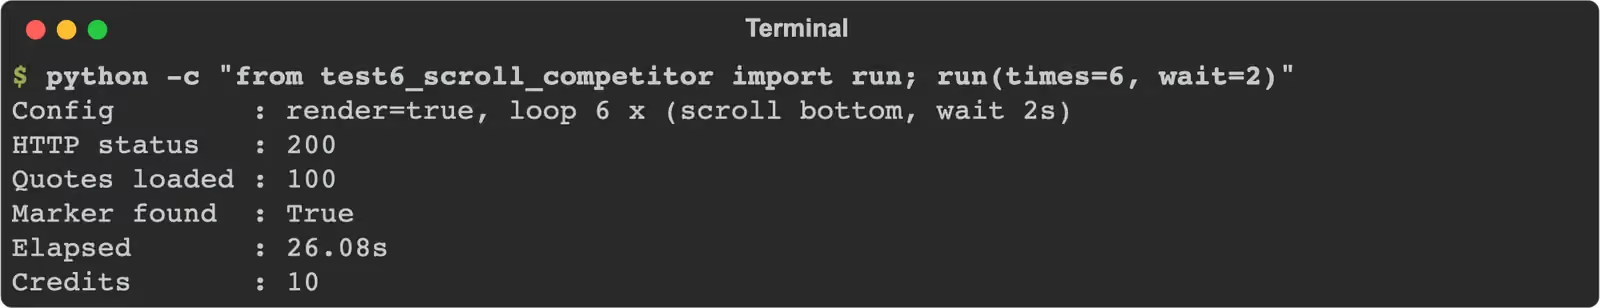
5/5 successful, median 26.08 s, 10 credits each: the instructions cost nothing on top of rendering.
| Test | Target | Configuration | Success | Median s | Slowest s | Units per success |
|---|---|---|---|---|---|---|
| #1 Static | books.toscrape.com | default | 10/10 | 2.69 | 6.40 | 1 credit |
| #2 JavaScript | quotes.toscrape.com/js/ | render=true | 10/10 | 9.84 | 41.12 | 10 credits |
| #3 Cloudflare | indeed.com | default | 10/10 | 8.82 | 16.70 | 10 credits |
| #4 DataDome | amway.com | premium, render, country_code=us | 3/10 | 43.28 | 57.17 | 40 credits |
| #5 Marketplace | walmart.com | default | 5/5 | 6.37 | 8.41 | 5 credits |
| #6 Scroll | quotes.toscrape.com/scroll | render, loop of 6 scrolls | 5/5 | 26.08 | 31.57 | 10 credits |
| #7 Escalation | amway.com | premium, render, country_code=us | 5/10 | 44.79 | 56.87 | 40 credits |
Gologin Web Unlocker and Cloud Browser: Same Targets, Same Method
What is the Gologin stack
Gologin Web Unlocker is a page retrieval API: one GET request returns the rendered HTML at one flat price per page, JavaScript included. It is stateless. Gologin Cloud Browser is the second layer: a cloud browser with a residential IP, billed by the hour and driven from Playwright or Puppeteer with a profile id, the same job a scraping browser does.
| Feature | Web Unlocker | Cloud Browser |
|---|---|---|
| Unit | page | browser hour |
| Entry price | $49 for 50k pages | $4.50 for 50 hours |
| JavaScript rendering | included | full browser |
| Failed requests | free | billed by time |
| Interaction | none | clicks, scroll, login |
| Connection | HTTP GET | Playwright, Puppeteer |
| IPs | managed | residential, per profile |
| Free start | 1,000 requests | 3 runs of 15 min |
Test #1: Static HTML page
We sent the same books.toscrape.com URL with the default request.
from common import unlocker
from markers import static_page

TARGET = "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html"

def run():
    response, elapsed = unlocker(TARGET)
    found = static_page(response.text)
    print(f"HTTP status   : {response.status_code}")
    print(f"Body          : {len(response.content):,} bytes")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    return response, elapsed, found

run()
Nine runs returned the title and price.
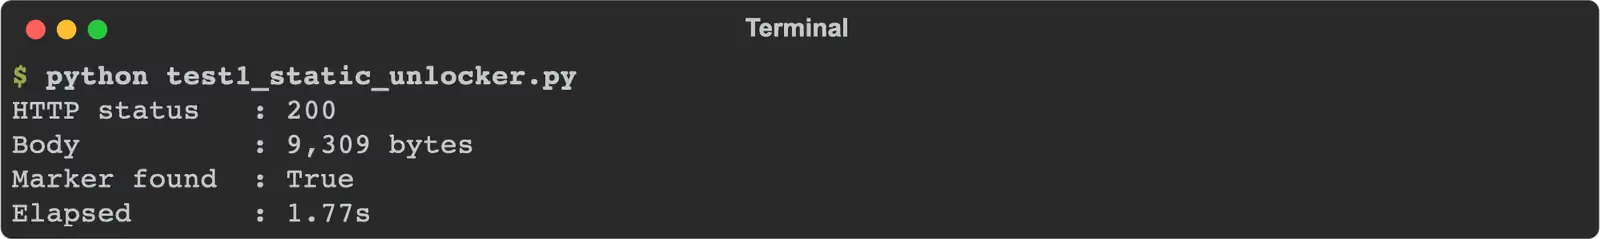
9/10 successful, median 1.77 s, 1 request each. One run ended in HTTP 503, not charged, and the slowest success took 26.95 s.
Test #2: JavaScript-rendered page
We sent quotes.toscrape.com/js/ with the same default request, no rendering option.
from common import unlocker
from markers import js_quotes

TARGET = "https://quotes.toscrape.com/js/"

def run():
    response, elapsed = unlocker(TARGET)
    found = js_quotes(response.text)
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    return response, elapsed, found

run()
The rendered quotes were in the body every time.
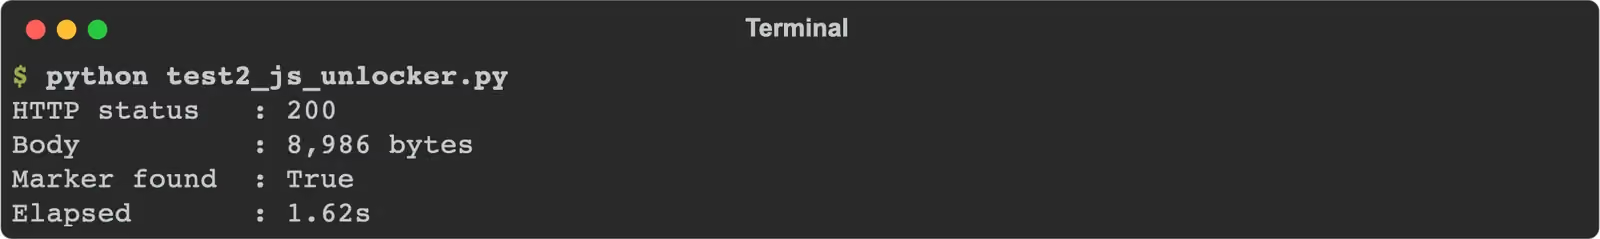
10/10 successful, median 1.48 s, 1 request each, with the slowest run at 4.15 s.
Test #3: Site behind Cloudflare
We sent the indeed.com search URL with the default request.
from common import unlocker
from markers import job_search

TARGET = "https://www.indeed.com/jobs?q=python+developer&l=New+York%2C+NY"

def run():
    response, elapsed = unlocker(TARGET)
    found = job_search(response.text)
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    return response, elapsed, found

run()
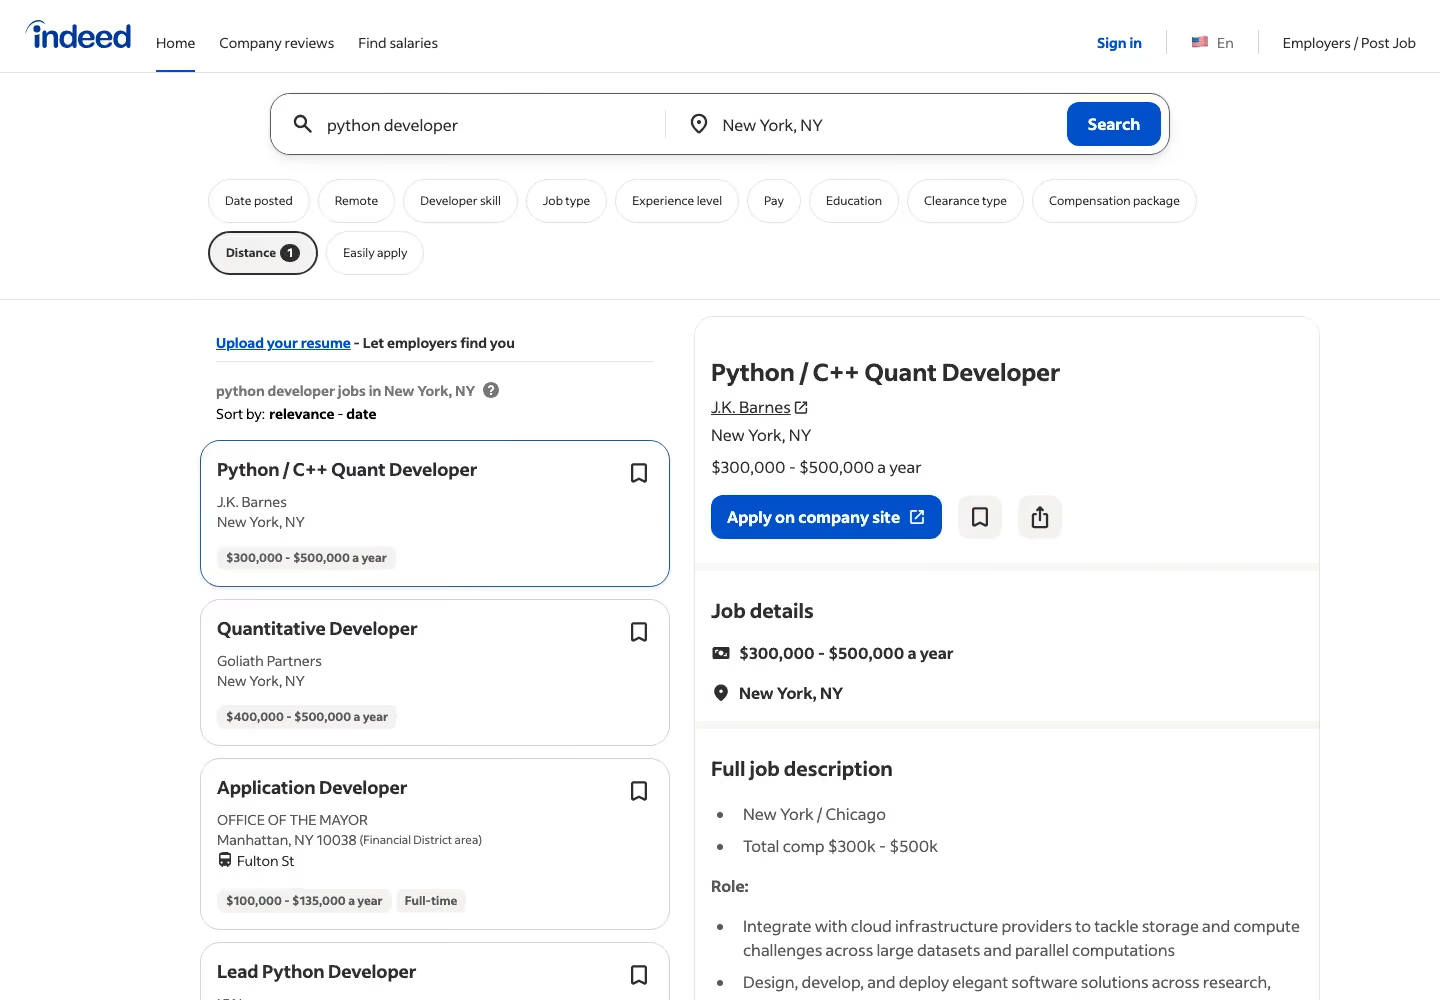
Every run returned the job list.
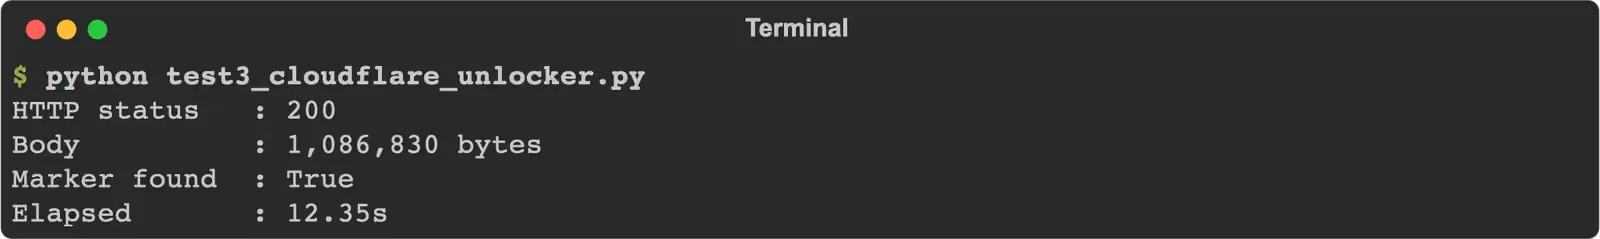
10/10 successful, median 12.41 s, 1 request each, about 3.6 s slower than ScraperAPI. For job data without writing a parser, Gologin also has a ready Indeed scraper.
Test #4: Site running DataDome
We sent the Amway Skin Care category URL with the default request.
from common import unlocker
from markers import category_page

TARGET = "https://www.amway.com/en_US/Shop/Beauty/Skin-Care/c/105"

def run():
    response, elapsed = unlocker(TARGET)
    found = category_page(response.text)
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    return response, elapsed, found

run()
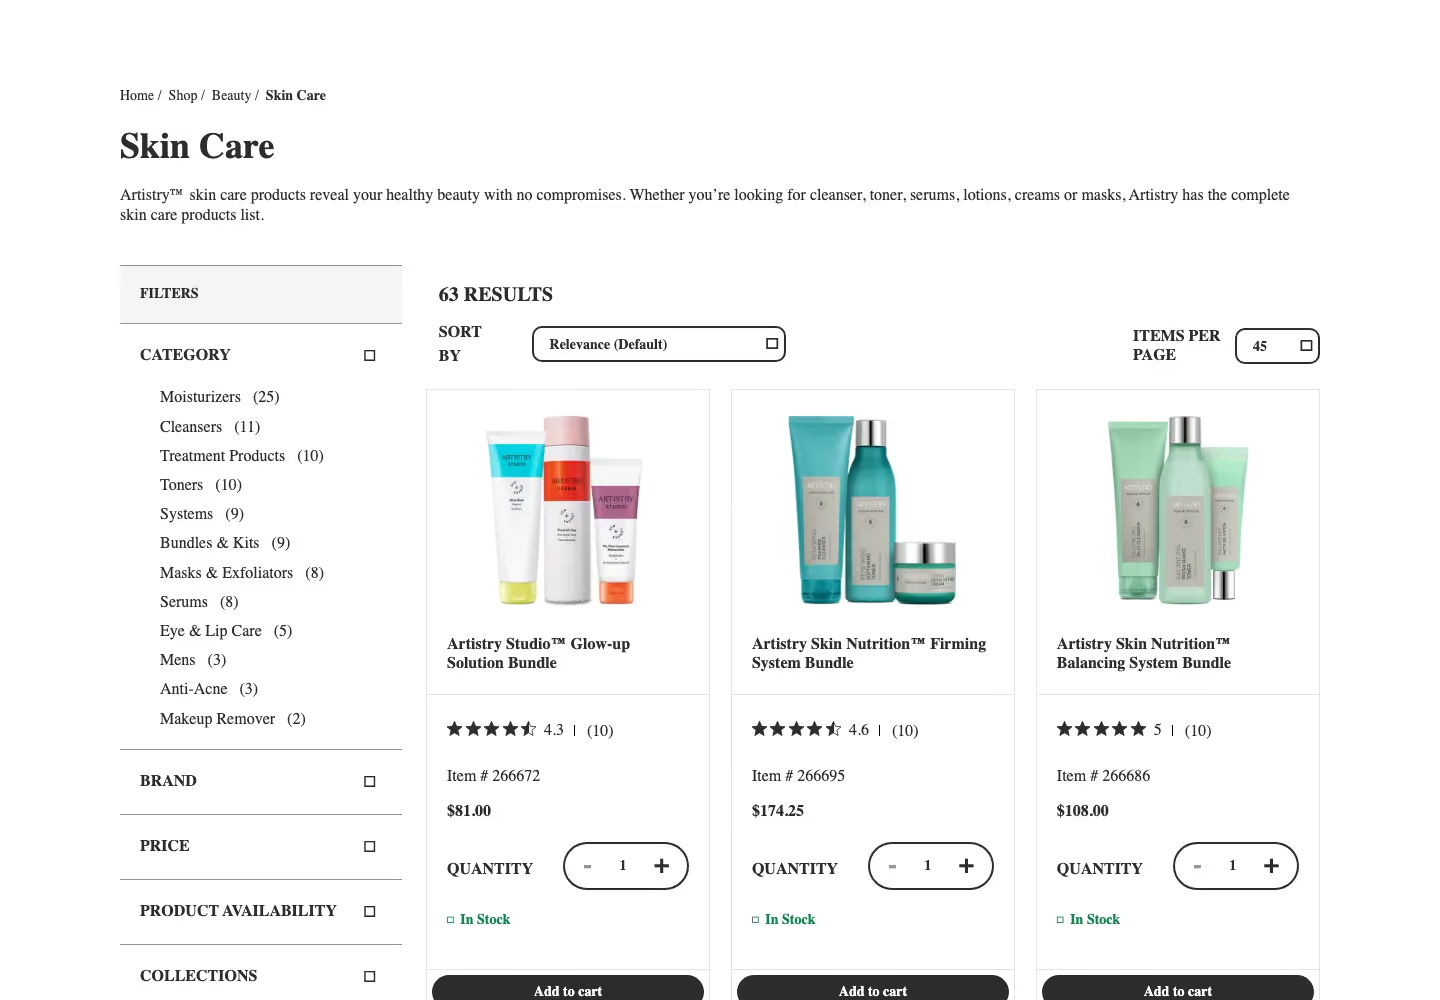
Every run returned the product grid with prices.
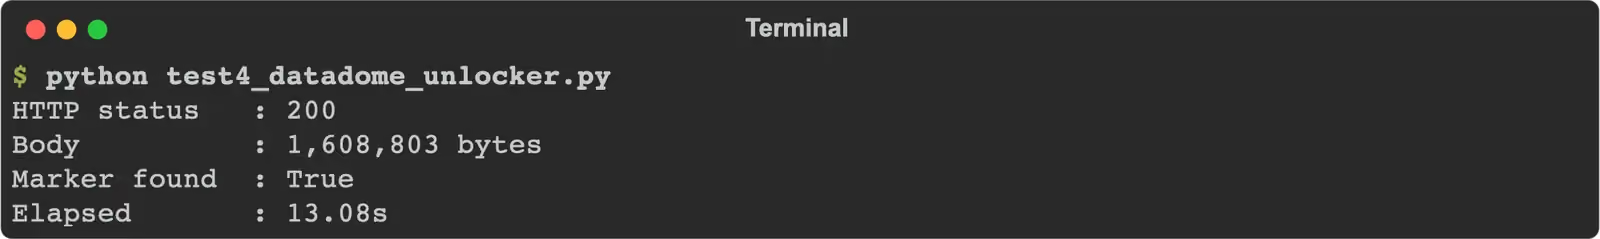
10/10 successful, median 12.86 s, 1 request each. The slowest run took 89.14 s.
Test #5: Marketplace product page
We sent the Walmart product URL with the default request.
from common import unlocker
from markers import product_page

TARGET = "https://www.walmart.com/ip/5689919121"

def run():
    response, elapsed = unlocker(TARGET)
    found = product_page(response.text)
    print(f"HTTP status   : {response.status_code}")
    print(f"Marker found  : {found}")
    print(f"Elapsed       : {elapsed:.2f}s")
    return response, elapsed, found

run()
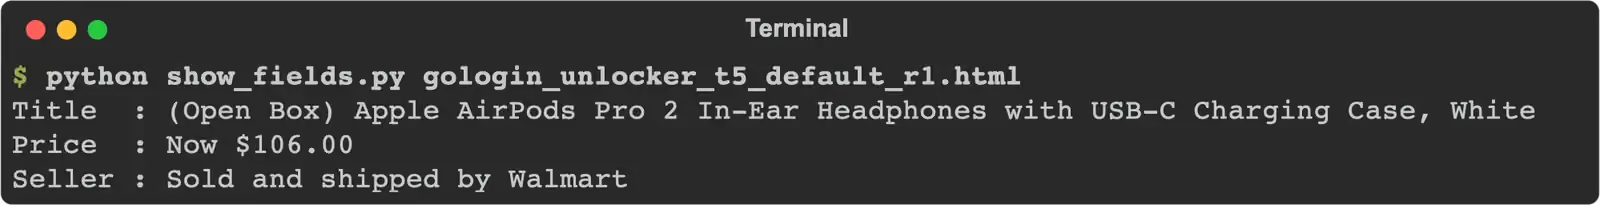
Every run returned the title and price.
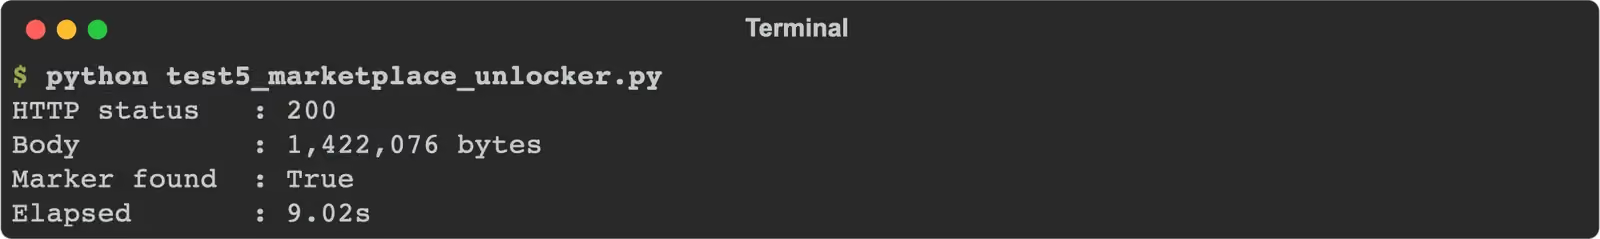
5/5 successful, median 9.02 s, 1 request each, about 2.7 s slower than ScraperAPI.
Test #6: Infinite scroll with Gologin Cloud Browser
We connected to Cloud Browser from Playwright with a profile id that has a Gologin US residential proxy and scrolled until 50 quotes were on the page.
from playwright.sync_api import sync_playwright
from common import key

TARGET = "https://quotes.toscrape.com/scroll"
ENDPOINT = "wss://cloudbrowser.gologin.com/connect?token={}&profile={}"

def run():
    with sync_playwright() as p:
        browser = p.chromium.connect_over_cdp(ENDPOINT.format(key("GOLOGIN_CLOUD_BROWSER_TOKEN"), key("GOLOGIN_PROFILE_ID")))
        page = browser.contexts[0].pages[0]
        page.goto(TARGET)
        quotes = page.locator("div.quote")
        for _ in range(20):
            if quotes.count() >= 50:
                break
            page.mouse.wheel(0, 5000)
            page.wait_for_timeout(1000)
        count = quotes.count()
        browser.close()
    print(f"Quotes loaded : {count}")
    print(f"Marker found  : {count >= 50}")
    return count

run()
The loop stopped at 50 quotes.
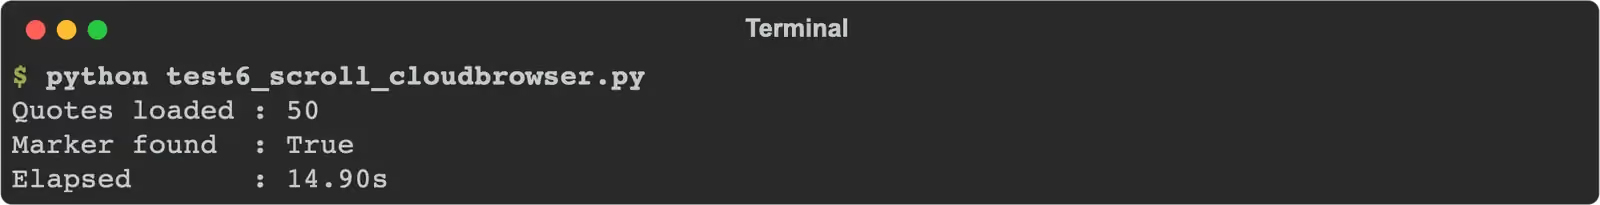
5/5 successful, median 14.90 s including the connection, about 0.004 browser hours each.
Test #7: Escalation to Cloud Browser on Amway
We opened the Amway category in Cloud Browser and waited for the product prices, with a new profile and US residential proxy per run.
from playwright.sync_api import sync_playwright
from common import fresh, key, new_profile, stop_session
from markers import category_page

TARGET = "https://www.amway.com/en_US/Shop/Beauty/Skin-Care/c/105"
ENDPOINT = "wss://cloudbrowser.gologin.com/connect?token={}&profile={}"

def run():
    profile = new_profile("amway-run")
    try:
        with sync_playwright() as p:
            browser = p.chromium.connect_over_cdp(ENDPOINT.format(key("GOLOGIN_CLOUD_BROWSER_TOKEN"), profile))
            page = browser.contexts[0].pages[0]
            page.goto(fresh(TARGET), wait_until="domcontentloaded")
            for _ in range(30):
                if category_page(page.content()):
                    break
                page.wait_for_timeout(1000)
            html = page.content()
            browser.close()
    finally:
        stop_session(profile)
    print(f"Marker found  : {category_page(html)}")
    return html

run()
Nine runs returned the full product grid.
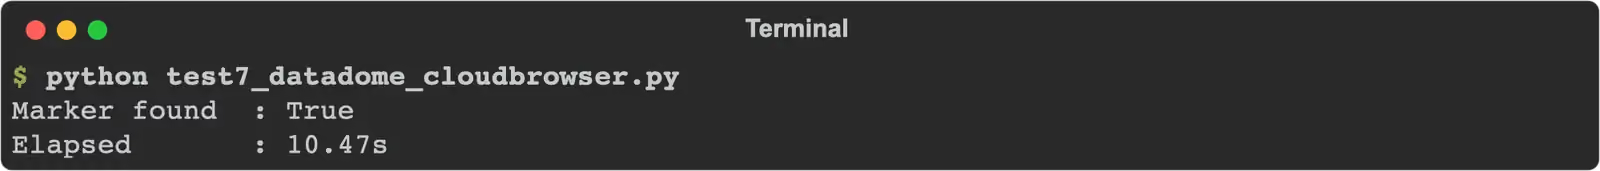
9/10 successful, median 10.47 s, about 0.003 browser hours each. The first run got a DataDome device check instead of the page.
| Test | Target | Configuration | Success | Median s | Slowest s | Units per success |
|---|---|---|---|---|---|---|
| #1 Static | books.toscrape.com | Web Unlocker, default | 9/10 | 1.77 | 26.95 | 1 request |
| #2 JavaScript | quotes.toscrape.com/js/ | Web Unlocker, default | 10/10 | 1.48 | 4.15 | 1 request |
| #3 Cloudflare | indeed.com | Web Unlocker, default | 10/10 | 12.41 | 23.58 | 1 request |
| #4 DataDome | amway.com | Web Unlocker, default | 10/10 | 12.86 | 89.14 | 1 request |
| #5 Marketplace | walmart.com | Web Unlocker, default | 5/5 | 9.02 | 15.58 | 1 request |
| #6 Scroll | quotes.toscrape.com/scroll | Cloud Browser, US residential | 5/5 | 14.90 | 15.68 | 0.004 h |
| #7 Escalation | amway.com | Cloud Browser, new profile per run | 9/10 | 10.47 | 16.92 | 0.003 h |
ScraperAPI Pricing and Credit System Explained
ScraperAPI pricing is credit-based. A normal request is 1 credit, render makes it 10, premium 10 or 25 with render, and ultra_premium 30 or 75. Sites add their own cost: we paid 5 credits for Walmart and 10 for Indeed because of the Cloudflare surcharge. On Amway, premium plus render came to 40.
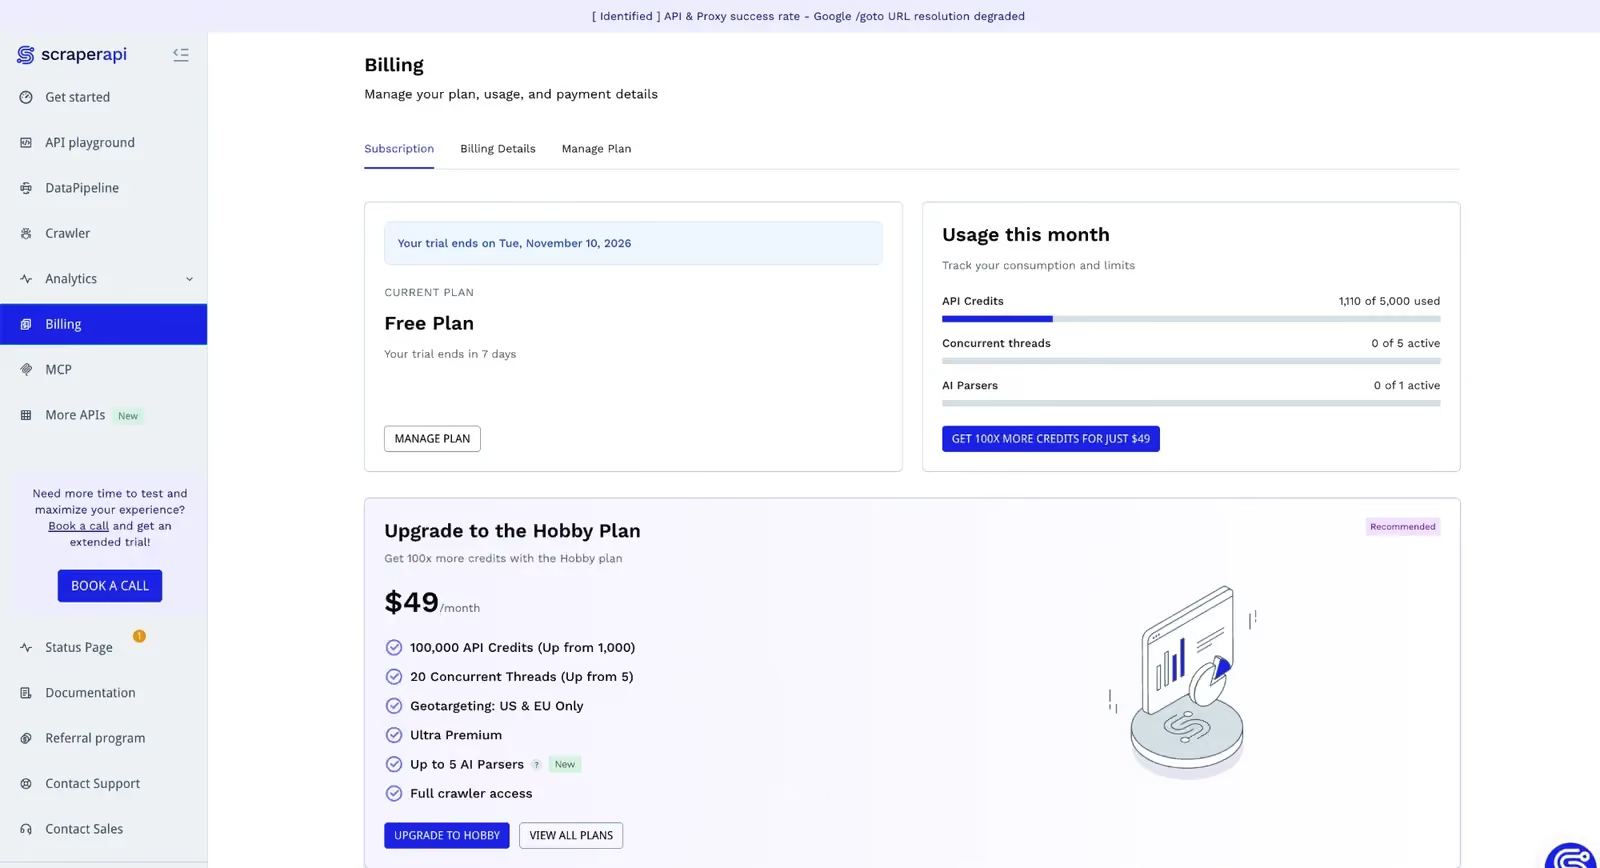
The billing rule is “you are only charged for successful requests, 200 and 404 status codes”, and our HTTP 500 runs were free. A 200 without the content still counts: we paid for 5 unrendered JavaScript pages and 17 Amway pages with no products. The trial gives 5,000 credits for 7 days with no card; all our tests used 1,110.
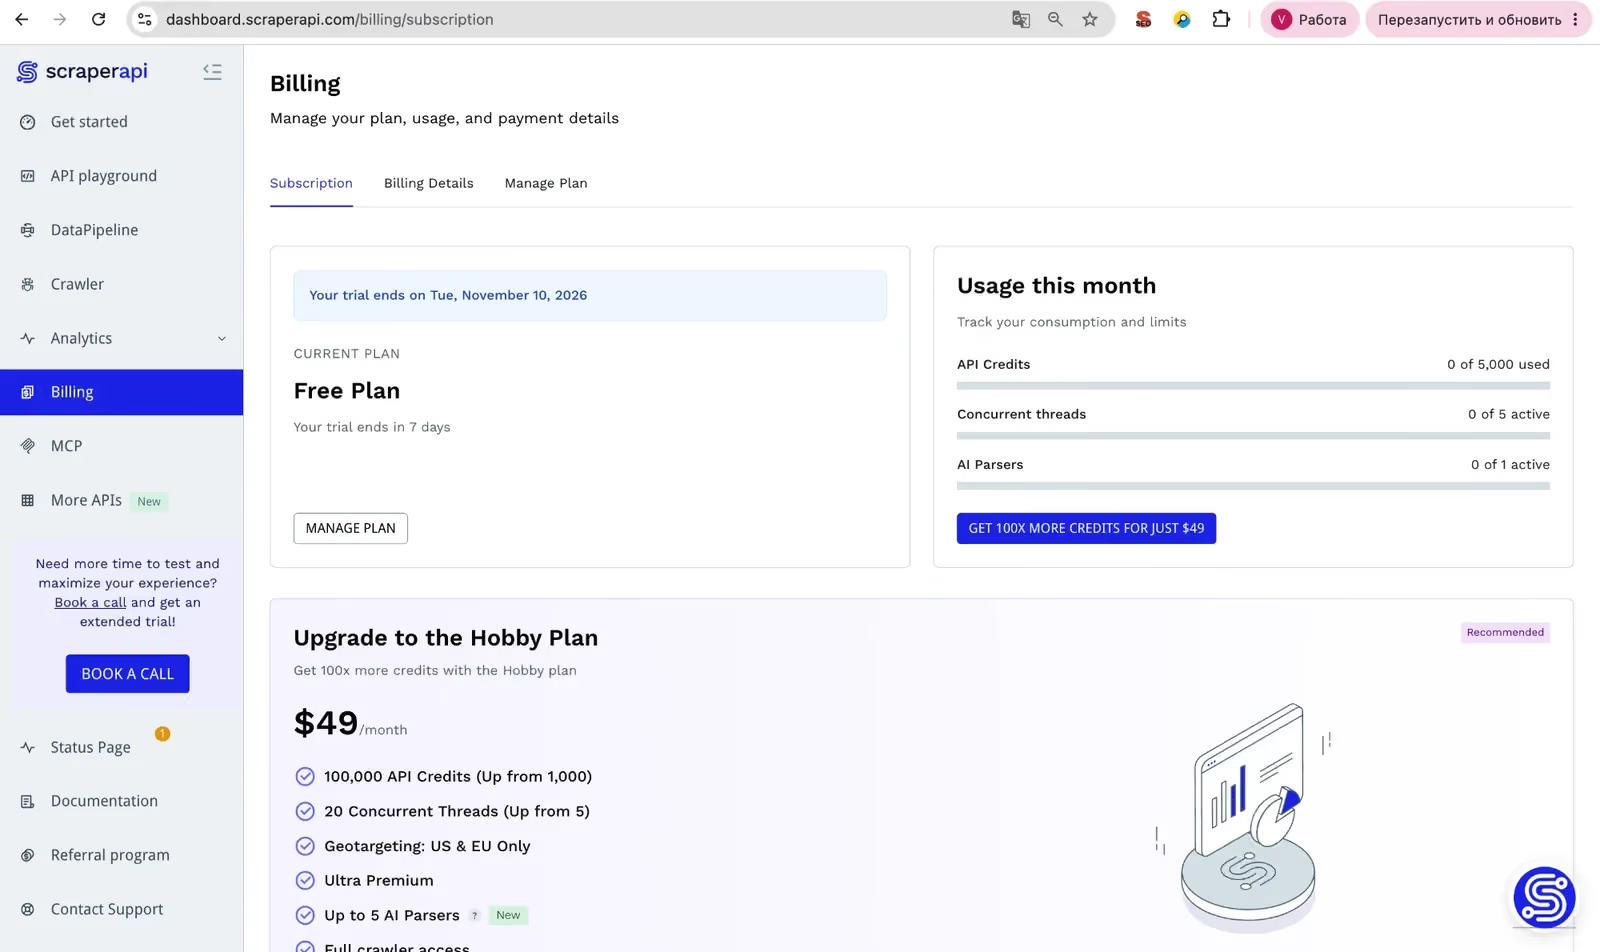
| Plan | Monthly price | Units included | Price per unit | Concurrency | Overage |
|---|---|---|---|---|---|
| Free trial | $0 | 5,000 credits, 7 days | free | 5 | none |
| Hobby | $49 | 100K credits | $0.49 per 1K | 20 | auto-upgrade |
| Startup | $149 | 1M credits | $0.15 per 1K | 50 | auto-upgrade |
| Business | $299 | 3M credits | $0.10 per 1K | 100 | auto-upgrade |
| Scaling | $475 | 5M credits | $0.095 per 1K | 200 | pay as you go |
| Professional | $975 | 10.5M credits | $0.093 per 1K | 300 | pay as you go |
| Advanced | $1,975 | 21.5M credits | $0.092 per 1K | 500 | pay as you go |
| Scenario (test) | Units per request | Cheapest plan $ (Hobby) | Comparable plan $ (Startup, $149) |
|---|---|---|---|
| Static (#1) | 1 | $0.49 | $0.15 |
| JavaScript (#2) | 10 | $4.90 | $1.49 |
| Cloudflare (#3) | 10 | $4.90 | $1.49 |
| DataDome (#4) | 40 | $19.60 | $5.96 |
| Marketplace (#5) | 5 | $2.45 | $0.75 |
| Scroll (#6) | 10 | $4.90 | $1.49 |
| DataDome, escalation (#7) | 40 | $19.60 | $5.96 |
These are the documented costs. Counting the billed empty pages, each Amway product grid at the reported setting in test #4 actually cost 120 credits, $58.80 per 1,000 on Hobby.
Gologin prices differently. Web Unlocker charges one flat price per returned page: $0.98 per 1,000 on Growth ($49 for 50k) and $0.75 on Professional ($149 for 200k), failed pages free. Cloud Browser bills browser time: $4.50 for 50 hours on Professional, so our 10.47 s Amway run comes to about $0.26 per 1,000 pages, plus proxy traffic above the plan allowance at $1/GB.
ScraperAPI Pros
- Fast on easy and mid pages: 2.69 s on the static page, 8.82 s on Indeed and 6.37 s on Walmart with the default request.
- Cheap static pages on a subscription: $0.49 per 1,000 on Hobby and $0.15 on Startup.
- Cost you can see: the sa-credit-cost header on every response and the free urlcost check matched the dashboard to the credit.
- More than HTML: Markdown, text, JSON autoparse and structured endpoints for large marketplaces and search engines.
ScraperAPI Cons
- Empty pages are charged: 5 unrendered JavaScript pages and 17 Amway pages without products were billed as successful requests.
- Costs climb fast on hard sites: the Amway page was 10 credits with no options and 40 with premium, render and US geo.
- Weak on our DataDome target: 3/10 at best on the trial, at a median of 43.28 s.
- Top tier off the trial: ultra_premium returned HTTP 403 on the free trial, so the trial does not show its best setting for hard sites.
ScraperAPI Limitations
- No browser product: no session to drive from Playwright; scroll and click steps run inside one rendered request, and the docs advise 3 to 4 actions.
- Geo depends on the plan: Hobby and Startup get only us and eu; country codes start on Business.
- 70-second window: the API retries for up to 70 seconds and then returns HTTP 500.
- Sessions are short and exclusive: session_number lasts 15 minutes and cannot be combined with premium or ultra_premium.
ScraperAPI vs Gologin: Head-to-Head Results
Both tools return pages from one request but price them differently. ScraperAPI adds credits for rendering, proxy tier and the site’s access protection. Gologin keeps retrieval in Web Unlocker at one price per page and moves live sessions to Cloud Browser.
| Aspect | ScraperAPI | Gologin stack |
|---|---|---|
| What you send | URL plus parameters | URL (Web Unlocker) or a Playwright session (Cloud Browser) |
| Rendering | render=true, 10 credits | included in Web Unlocker |
| Price unit | credit, by parameter and site | page (Web Unlocker), hour (Cloud Browser) |
| Interaction | rendering instructions inside one call | full browser session |
| Structured output | autoparse and structured endpoints | HTML, Markdown, text, JSON (product page) |
ScraperAPI alternative: when Gologin is a better choice
| Scenario | Better fit | From our tests |
|---|---|---|
| Sites running DataDome | Web Unlocker | 10/10 against 3/10 on test #4 |
| JavaScript-heavy pages at volume | Web Unlocker | 1.48 s against 9.84 s, 1 request against 10 credits |
| Pages that need scrolling or clicks | Cloud Browser | 14.90 s against 26.08 s on test #6 |
| A hard page that needs a real browser | Cloud Browser | 9/10 at 10.47 s against 5/10 at 44.79 s on test #7 |
| Logged-in or multi-step flows | Cloud Browser | not tested; documented session product |
| Test | ScraperAPI success | ScraperAPI median s | Gologin success | Gologin median s |
|---|---|---|---|---|
| #1 Static | 10/10 | 2.69 | 9/10 | 1.77 |
| #2 JavaScript | 10/10 | 9.84 | 10/10 | 1.48 |
| #3 Cloudflare | 10/10 | 8.82 | 10/10 | 12.41 |
| #4 DataDome | 3/10 | 43.28 | 10/10 | 12.86 |
| #5 Marketplace | 5/5 | 6.37 | 5/5 | 9.02 |
| #6 Scroll | 5/5 | 26.08 | 5/5 | 14.90 |
| #7 Escalation | 5/10 | 44.79 | 9/10 | 10.47 |
| Scenario | ScraperAPI, cheapest plan | ScraperAPI, comparable plan | Gologin, entry plan | Gologin, comparable plan |
|---|---|---|---|---|
| Static (#1) | $0.49 | $0.15 | $0.98 | $0.75 |
| JavaScript (#2) | $4.90 | $1.49 | $0.98 | $0.75 |
| Cloudflare (#3) | $4.90 | $1.49 | $0.98 | $0.75 |
| DataDome (#4) | $19.60 | $5.96 | $0.98 | $0.75 |
| Marketplace (#5) | $2.45 | $0.75 | $0.98 | $0.75 |
| Scroll (#6) | $4.90 | $1.49 | $0.37 | $0.33 |
| DataDome in a browser (#7) | $19.60 | $5.96 | $0.26 | $0.23 |
| Feature | ScraperAPI | Gologin stack |
|---|---|---|
| Pricing model | credits by parameter and site | per page, flat; browser per hour |
| JS rendering | render=true, 10 credits | included |
| Geo-targeting level | us and eu on Hobby and Startup, country from Business | country, state, city (product page) |
| Proxy tiers | standard, premium, ultra_premium (paid plans) | managed; residential on Cloud Browser |
| Sticky session, minutes | 15 (session_number) | Cloud Browser session |
| Output formats | HTML, Markdown, text, JSON, CSV | HTML, Markdown, text, JSON (product page) |
| Structured extraction | autoparse, structured endpoints | not documented |
| Screenshots | yes, screenshot=true | listed in the docs overview |
| Browser-level control | no | Gologin Cloud Browser |
| Batch and webhooks | Async API, 50,000 URLs, webhooks | up to 1,000 URLs, webhooks (product page) |
| Failure signalling | HTTP status, sa-credit-cost | HTTP status |
| Charged responses | every 200 and 404 | successful pages only |
| Free trial | 5,000 credits, 7 days | 1,000 requests, 7 days |
ScraperAPI won tests 3 and 5 on speed and was cheaper on the static page; on test #1 it also had the better success rate, 10/10 against 9/10. Gologin won tests 2, 4, 6 and 7. The gap is widest on test #4: 10/10 at 12.86 s for Web Unlocker against 3/10 at 43.28 s for ScraperAPI.
On cost, ScraperAPI Hobby beats Web Unlocker’s entry plan on static pages, $0.49 against $0.98 per 1,000, and Startup matches it on Walmart at $0.75. Once rendering or a protection surcharge applies, the order flips: $4.90 against $0.98 on JavaScript and Indeed pages, $19.60 against $0.98 on Amway.
When the Unlocker Fails: Escalation to Cloud Browser
Web Unlocker’s only loss in tests 1 to 5 was one HTTP 503 on the static page, so we ran test #7 on the hardest page instead: the Amway category in Gologin Cloud Browser. With a new profile and US residential proxy per run, Cloud Browser returned the grid 9/10 at a median of 10.47 s, about 2.9 browser hours per 1,000 pages, $0.26 on Professional before proxy traffic. ScraperAPI has no browser product, so its side ran its most expensive working configuration, premium plus render plus US geo: 5/10 at 44.79 s, 40 credits, $19.60 per 1,000 on Hobby.
The rule: Web Unlocker for pages you can fetch in one request, Cloud Browser when the page needs scrolling, clicks or a login, as on test #6 (14.90 s against 26.08 s). ScraperAPI does both inside one API, with browser steps limited to what one rendered request can hold.
Frequently Asked Questions
Is ScraperAPI worth it in 2026?
For static pages, Indeed and Walmart, yes: it returned all three 10/10 or 5/5, faster than Web Unlocker on the last two, at $0.49 to $4.90 per 1,000 on Hobby. On our DataDome target it got 3/10 at 40 credits a request, and it bills empty 200 pages. Test your own targets on the 5,000 free credits first.
How much does ScraperAPI cost per 1,000 pages?
It depends on the parameters and the site. On Hobby ($49 for 100K credits) a static page costs $0.49 per 1,000, a rendered page or a page behind Cloudflare $4.90, a Walmart page $2.45, and our DataDome page $19.60 with premium, render and US geo. Gologin Web Unlocker is $0.98 per 1,000 for any page.
Does ScraperAPI charge for failed requests?
Not for errors: our HTTP 500 runs were free. But it charges every HTTP 200 and 404, whatever the page contains. We paid 1 credit each for 5 unrendered JavaScript pages and 10 to 40 credits each for 17 Amway pages that showed “A system error has occurred” and no products.
Is there a ScraperAPI alternative for DataDome sites?
On the Amway category page, which runs DataDome, ScraperAPI got 3/10 at best on the trial, with premium, render and country_code=us, at a median of 43.28 s. Gologin Web Unlocker returned the full product grid 10/10 with the default request at a median of 12.86 s.
Does ScraperAPI have a browser product like Gologin Cloud Browser?
No. ScraperAPI offers rendering instructions (click, input, loop, scroll, wait) inside one rendered request. On our infinite-scroll test they loaded 100 quotes 5/5 at 26.08 s for 10 credits. Gologin Cloud Browser runs a full Playwright session and reached 50 quotes 5/5 at 14.90 s.
ScraperAPI Review Verdict: Which One Should You Use?
There is no single best web scraping API across these seven targets.
What ScraperAPI does better or cheaper than the Gologin stack:
- Indeed and Walmart: 8.82 s against 12.41 s, and 6.37 s against 9.02 s, with the default request.
- Static pages: 10/10 against 9/10, and $0.49 per 1,000 on Hobby against $0.98.
- Structured data and cost signals: autoparse, structured endpoints and an sa-credit-cost header on every response.
Where the Gologin stack was weaker in this test:
- Static page: one Web Unlocker run ended in HTTP 503 and one success took 26.95 s.
- Speed on Indeed and Walmart: 3.6 s and 2.7 s slower than ScraperAPI.
- Slow tail on Amway: the slowest Web Unlocker run took 89.14 s.
- Cloud Browser on Amway: one of ten runs got a DataDome device check.
What the Gologin stack does better or cheaper than ScraperAPI:
- Web Unlocker on DataDome: 10/10 against 3/10 on test #4.
- Web Unlocker on JavaScript pages: 1.48 s against 9.84 s on test #2, 1 request against 10 credits.
- One price per page: $0.98 per 1,000 on Amway against $19.60 on ScraperAPI Hobby, and empty pages are not billed.
- Cloud Browser for interaction: 14.90 s against 26.08 s on test #6, and 9/10 against 5/10 on test #7.
Choose ScraperAPI if you need static pages, Indeed-type or Walmart-type pages fast on a low-cost plan, or ready JSON for the sites its structured endpoints cover.
Choose Gologin if you need pages from sites running DataDome, JavaScript-heavy pages at one flat price, or a real browser session for scrolling and multi-step pages.
Conclusion
ScraperAPI is a quick, transparent API for static pages and for sites its default request gets through. On our DataDome target it reached 40 credits a request for 3 grids in 10, billing empty pages on the way. Gologin Web Unlocker returned that page every time at one flat price, and Cloud Browser covers the session jobs that ScraperAPI fits into one request.
Gologin Web Unlocker gives you 1,000 free requests for 7 days with no credit card, enough to repeat these tests on your own pages.